Running Mojo on Android - in a Weekend!
I got Mojo running on Android, posted the first results on X, and Chris Lattner replied:
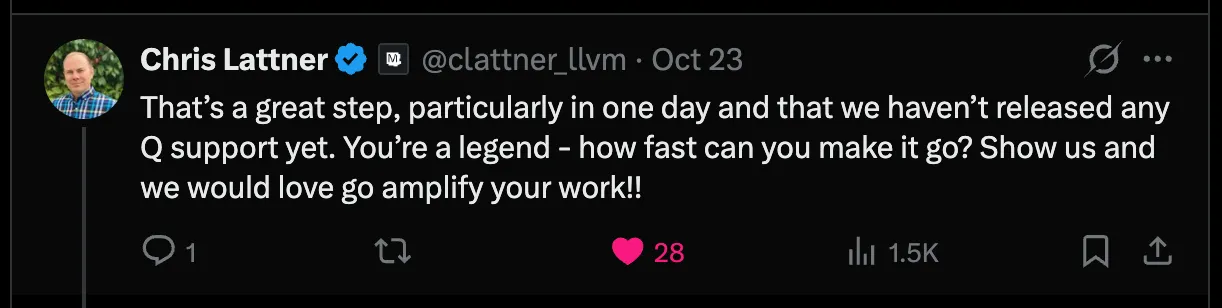
“How fast can you make it go?” was all the encouragement I needed to make it go brrr.
A few days later, Bonsai 2 2B was running at roughly 70 tokens/s on my Galaxy S26.
But the part I’m most excited about isn’t the number. It’s a native Mojo inference implementation, running through an Android GPU backend built on Modular’s compiler and MAX infrastructure. No llama.cpp underneath it.
And it didn’t stop at the S26. The same approach now runs Bonsai 2B, 4B, and 9B on Adreno, Mali, and Samsung Xclipse GPUs, with competitive or better decode throughput against the tested llama.cpp Vulkan baseline.
After listening to Abdul Dakkak on GPU Mode say “Mojo compiler has no clue its compiling for GPUs.”, I wanted to see how far I could extend the Modular stack. This got much further, much faster, than I expected.
Exact values and variation
- 2B: 68.41 ± 5.79 tok/s
- 4B: 37.41 ± 0.05 tok/s
- 9B: 20.57 ± 1.33 tok/s
- 2B: 51.74 ± 0.65 tok/s
- 4B: 27.20 ± 0.40 tok/s
- 9B: 16.69 ± 0.43 tok/s
The curve shows the latest Mojo results against the recorded Prism reference.
Almost all of the optimization work targeted 2B. Seeing the larger models land above the reference too was the first indication that the work was carrying beyond one carefully tuned demo.
A Very Agentic Few Days
The bring-up story is quite funny. I was working on my “80/20 Compiler” and extending it to Android. On the way to a lecture, I saw that MAX had become source-available.
I asked my agent to do a cursory check of what an Android port would involve. When I got back, Tibo had announced another usage reset for 10 AM the next morning. I also had a mid-semester exam at Columbia University to prepare for.
So that night I was burning brain cells for the exam, and burning tokens on the Android port in the background.
Almost all of the development was agent-driven, using Sol and Luna on a $20 plan. No expensive frontier-model setup, just a lot of experiments and validation. What surprised me was how far agents could get by extending the existing abstractions in Mojo and MAX.
The one-day milestone was the initial bring-up. The following days were about turning “it runs” into something worth running.
Bringing Mojo to Android
The first successful execution was deliberately small: a Mojo matrix multiplication compiled for Android ARM64, called through the C ABI, and run on the phone’s CPU on October 23. That established a CPU foothold.
Then came simple GPU matrix multiplication through the new OpenCL plugin. This slowly expanded to a linear, activation, transformer block and finally a complete language model: SmolLM 2.
What actually runs on Android?
- Added in this fork. Model + GPU kernelsMojo forward pass, packed Bonsai weights, shared max.gpu APIs.
- Reused Modular. Mojo compiler + LLVMExisting frontend, optimizations, and offload infrastructure.
- Added in this fork. ARM64 + OpenCL artifactsNative host code; new backend emits kernel bundles and argument metadata.
- Reused Modular. Forward → DeviceContextNative model orchestration through existing buffer, stream, and event APIs.
- Added in this fork. OpenCL runtime pluginImplements the MAX HAL: load, allocate, dispatch, synchronize.
- Vendor-provided. OpenCL driver → GPUVendor compiles OpenCL C; Adreno or generic kernels execute.
Added in this fork
- Compiler target: Mojo GPU kernels → OpenCL C bundles + argument metadata.
- Runtime plugin: implements the existing MAX HAL for discovery, buffers, queues, dispatch, and events. Maps typed buffer views to OpenCL allocations and offsets.
- Model ports: native ARM64 Mojo forward passes orchestrate inference and launch the GPU kernels.
Reused from Modular
- Mojo’s compiler frontend, LLVM optimization, and offload infrastructure.
DeviceContextAPIs for device buffers, streams, and events.
While implementing the OpenCL backend, I also ran into a few interesting assumptions baked into the existing compiler and runtime, largely shaped by the GPU backends they already supported. OpenCL’s different memory and execution model exposed some edge cases: lifetime checking for associated storage types, pointer-provenance loss in fused GPU kernels, and device assertions on hardware where native traps were ineffective.
These required fixes beyond the OpenCL backend itself. The full debugging history is documented in the repo’s docs.
From Running to Running Fast
The optimization loop was simple: ask the agent to profile the workload, identify the bottleneck, rank candidate changes, and test them.
Bonsai 2 2B was a useful target because it uses an unusual hybrid architecture with ternary-quantized weights, thus being small enough to easily fit in memory.
Memory traffic
We know in theory that decode is memory bound. But seeing it affect performance as much as it did was very interesting.
For example, in one optimisation loop, the model’s weights and state were already resident on the GPU. But the waste was inside GPU execution: packed projections wrote partial sums to global memory, and separate rowwise kernels read them back to finish the reductions.
Calibrated counter analysis estimated approximately 43.5 MB of partial-sum writes and 45.5 MB of subsequent reads per decoded token. Those measurements gave the agent a concrete target: combine more work before writing the partials out.
This is just one stage. But memory related optimisations keep appearing throughout the process.
Experiment selection: why the headline is not 80 tok/s
There were short runs near 80 tokens/s. I would have liked that headline better.
Most of decode time was spent in packed-weight projection kernels. Thus I created a synthetic benchmark for this task and ran the model optimisation loop on it. The resulting kernel peaked at 78.10 tok/s!!! However, the results were very inconsistent going all the way down to 65.10 tok/s. The leading theory is that it somehow triggered thermal throttling earlier thus over sustained runs, the mean was worse.
A Hexagon hybrid path likewise ran, but its final difference from GPU-only was too small to establish a useful gain. GPU-only stayed the default.
The roughly-70-tokens/s result comes from the retained implementation. It is not the sum of every promising experiment in the notebook.
Beyond Adreno: Mali and Xclipse
Once the S26 path worked, I wanted to try testing it on other hardware chips too. For this, I created a portable Mojo verion. It shares most of the Adreno implementation, except it removes few Adreno specific calls which creeped in because most of the development was done on my S26.
MediaTek with Mali GPU
The first portable Mali result was painfully slow: about 1.75 tokens/s compared the llama.cpp baseline.
The successful change was in the runtime plugin: call clFlush after each kernel enqueue. This issues pending commands toward the device without requiring each kernel to finish before enqueueing the next one; it is different from inserting clFinish after every launch.
This improvement instantly jumped us over the llama.cpp baseline across the model family.
Exact values and variation
- 2B: 10.07 ± 0.01 tok/s
- 4B: 6.88 ± 0.04 tok/s
- 9B: 4.98 ± 0.55 tok/s
- 2B: 6.73 ± 0.01 tok/s
- 4B: 3.01 ± 0.03 tok/s
- 9B: 0.76 ± 0.02 tok/s
Samsung Exynos with Xclipse GPU
The Galaxy S24 FE uses Samsung’s Xclipse 940. The generic path runs there too. The result is more mixed: a small deficit at 2B, an advantage at 4B, and a close result at 9B.
Exact values and variation
- 2B: 20.37 ± 0.62 tok/s
- 4B: 11.79 ± 0.04 tok/s
- 9B: 7.59 ± 0.11 tok/s
- 2B: 21.55 ± 0.84 tok/s
- 4B: 9.54 ± 0.07 tok/s
- 9B: 7.23 ± 0.04 tok/s
Encouraging results! But I spent exponentially less time on these portable paths than on Bonsai 2 2B on the S26. I borrowed phones from my friends for the tests, so I had much less time for validation and testing.
But I am extremely happy with running the three model sizes across vendors with atleast comparable or better performance.
Beyond Bonsai: Testing Qwen
I also ported Qwen3-1.7B and Qwen3.5-2B. These retain the actual mixed Q4_K_M tensors rather than substituting easier weights. They reuse some of the existing model and kernel work, but did not get a comparable optimization campaign.
They run, but are much slower than llama.cpp Vulkan baseline.
That is a clear next challenge. These results show how much work remains before it becomes a broadly competitive quantized inference backend.
Benchmark Methodology
All decode results use the tg128 workload: 128 sequential token evaluations, following llama-bench’s measurement methodology. PrismML’s llama.cpp Vulkan backend serves as the reference, while Mojo uses an equivalent benchmark harness running through the new Android OpenCL backend.
Exact commands, model files, configurations, and reproduction instructions are available in the repository README.
Try It, Break It, Tell Me What I Missed
This is my personal experimental fork. I have tried to make sure, and test that the benchmark numbers can be reproduced. But it is still very much a development tree!
A timely reminder about measurement and benchmarking.
Artur Chakhvadze, October 26, 2026
Benchmarking is hard, especially on mobile GPUs. If you spot a mismatched comparison, a missing control, or a reason these numbers do not mean what I think they mean, I would love to hear it. I am sharing the measurements with the code so I can find out.
What started as a one-day experiment now works across three mobile GPU families. There’s plenty left to optimize, but I’m excited by how much and how easily the Modular stack could be extended to hardware it wasn’t originally targeting.
And Chris, if you’re reading this: I tried to make it go brrr. 🔥